commit c59cf5181666c583bc6c27f11a0450100237687a
map588 <map588@pitt.edu>
2026-09-27 02:14:20 -0400

Add LuaSnip converter with tests

The converter escapes $, \ and }, so LuaSnip does not parse shell
variables and make macros as snippet variables. Tab stops use the
${n} form, so a placeholder followed by a digit does not become
$10. Common Lisp maps to the lisp filetype. Prefixes join the path
parts, so nested templates cannot collide. The output includes the
package.json that the from_vscode loader needs. Add --output and
--dry-run. Tests use Hypothesis for the escape round trip. The
README documents the Neovim workflow.
 README.md                  |  71 ++++++++++++++----
 convert_to_luasnip.py      | 176 +++++++++++++++++++++++++++++++++++++++++++++
 test_convert_to_luasnip.py |  92 ++++++++++++++++++++++++
 3 files changed, 325 insertions(+), 14 deletions(-)
diff --git a/README.md b/README.md
index c308a7e..4cf5530 100644
--- a/README.md
+++ b/README.md
@@ -1,14 +1,10 @@
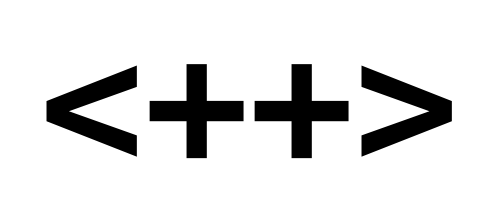
-Templates for all kinds of things. Just read a file into your editor at the cursor and jump to the `<++>` locations.
+Templates for all kinds of things. Read a file into your editor at the cursor
+and jump to the `<++>` locations.
A [therealtruex.com](https://therealtruex.com) project.
-vim config:
-```
-map <leader><Space> /<++><CR>dt>a<BS>
-```
-
Here is one such template:
```
(defpackage :<++>-system (:use :cl :asdf))
@@ -29,21 +25,68 @@ Here is one such template:
:depends-on (<++>))
```
+# Layout
+
+One directory per language: `c`, `cl` (Common Lisp), `sh` (POSIX shell),
+`sed`, `awk`, `make`, `vim`, `html`. A few loose templates sit at the root
+(`openrc.init`, `git-config-branch`, `uad.json`).
+
+Two kinds of file live here:
+
+- **Templates** contain `<++>`. Read them in and fill the gaps.
+- **Cheat sheets** contain no `<++>` (for example `sed/TLDR`, `vim/use-g-v`,
+ most of `sh/`). They are notes to read or `:read` in whole. The snippet
+ converter skips them.
+
# Using with Vim
```vim
:read /path/to/tmpl/thing
```
+Add a shortcut on your leader key that jumps to the next `<++>`, deletes it,
+and leaves you in insert mode.
-Make sure to add a templating shortcut to your leader key to jump to
-the `<++>` spots.
+Vimscript:
```vim
- -- Templating shortcut
- map("n", "<leader><Space>", "/<++><CR>dt>a<BS>", { desc = "Jump to next template placeholder" })
+map <leader><Space> /<++><CR>dt>a<BS>
+```
+
+Lua:
+```lua
+map("n", "<leader><Space>", "/<++><CR>dt>a<BS>", { desc = "Jump to next template placeholder" })
```
-POSIX shell tricks
-Many of the shell tricks taken from here:
-https://www.etalabs.net/sh_tricks.html
-Especially for-find, a nightmare fixed-point solution.
+# Using with Neovim and LuaSnip
+
+`convert_to_luasnip.py` turns every template into a VSCode-format snippet.
+Each language becomes one JSON file, and a `package.json` lists them for the
+LuaSnip loader.
+
+```sh
+python3 convert_to_luasnip.py --dry-run # list what would be written
+python3 convert_to_luasnip.py # write to ~/.config/nvim/snippets
+python3 convert_to_luasnip.py --output some/dir # write elsewhere
+```
+
+Load the output in your Neovim config:
+```lua
+require("luasnip.loaders.from_vscode").lazy_load({
+ paths = { vim.fn.stdpath("config") .. "/snippets" }
+})
+```
+
+The snippet prefix is the path with dashes: `c/main.c` is `c-main`,
+`sh/trap/cleanup-temp` is `sh-trap-cleanup-temp`. Type the prefix, press Tab,
+and Tab again to move between the placeholders.
+
+Tests:
+```sh
+python3 -m pip install pytest hypothesis
+python3 -m pytest
+```
+
+# POSIX shell tricks
+
+Many of the shell tricks come from https://www.etalabs.net/sh_tricks.html,
+especially `sh/for-find`, a nightmare fixed-point solution.
diff --git a/convert_to_luasnip.py b/convert_to_luasnip.py
new file mode 100644
index 0000000..f7e0e56
--- /dev/null
+++ b/convert_to_luasnip.py
@@ -0,0 +1,176 @@
+#!/usr/bin/env python3
+"""Convert template files with <++> placeholders to LuaSnip VSCode-format snippets.
+
+Each language directory becomes one <lang>.json file. A package.json lists
+them so the LuaSnip from_vscode loader can find them.
+"""
+
+import argparse
+import json
+import re
+from pathlib import Path
+from typing import Any, Dict, List, Optional, Tuple
+
+# Map from template directory name to Neovim filetype.
+LANGUAGE_MAP = {
+ "c": "c",
+ "cl": "lisp",
+ "sh": "sh",
+ "html": "html",
+ "make": "make",
+ "awk": "awk",
+ "vim": "vim",
+ "sed": "sed",
+}
+
+# Map from root-level template file name to Neovim filetype.
+ROOT_FILE_MAP = {
+ "openrc.init": "sh",
+ "git-config-branch": "gitconfig",
+ "uad.json": "json",
+}
+
+PLACEHOLDER_RE = re.compile(r"<\+\+>")
+
+
+def escape_snippet_text(text: str) -> str:
+ """Escape the characters that VSCode snippet syntax treats as special."""
+ return re.sub(r"([\\$}])", r"\\\1", text)
+
+
+def convert_placeholders(content: str) -> Tuple[str, int]:
+ """Replace each <++> with a numbered tab stop. Escape all other text."""
+ parts = PLACEHOLDER_RE.split(content)
+ body = escape_snippet_text(parts[0])
+ for index, part in enumerate(parts[1:], start=1):
+ body += "${" + str(index) + "}" + escape_snippet_text(part)
+ return body, len(parts) - 1
+
+
+def generate_snippet_name(filepath: Path, template_dir: Path) -> str:
+ """Join the path parts with dashes: sh/trap/cleanup-temp -> sh-trap-cleanup-temp."""
+ rel_path = filepath.relative_to(template_dir).with_suffix("")
+ return "-".join(rel_path.parts)
+
+
+def get_description(filepath: Path, template_dir: Path) -> str:
+ """Describe the snippet by its path."""
+ rel_path = filepath.relative_to(template_dir)
+ return f"{rel_path} template"
+
+
+def process_template_file(filepath: Path, template_dir: Path) -> Optional[Dict[str, Any]]:
+ """Read one template file. Return None when it is not a template."""
+ try:
+ content = filepath.read_text(encoding="utf-8").strip()
+ except (UnicodeDecodeError, PermissionError):
+ return None
+
+ if not content or not PLACEHOLDER_RE.search(content):
+ return None
+
+ body, _ = convert_placeholders(content)
+ return {
+ "prefix": generate_snippet_name(filepath, template_dir),
+ "body": body.split("\n") + ["$0"],
+ "description": get_description(filepath, template_dir),
+ }
+
+
+def language_for(filepath: Path, template_dir: Path) -> Optional[str]:
+ """Return the Neovim filetype for a template path, or None when unknown."""
+ rel_path = filepath.relative_to(template_dir)
+ if len(rel_path.parts) > 1:
+ return LANGUAGE_MAP.get(rel_path.parts[0])
+ return ROOT_FILE_MAP.get(rel_path.name)
+
+
+def collect_templates_by_language(template_dir: Path) -> Dict[str, List[Dict[str, Any]]]:
+ """Collect all templates under template_dir, grouped by filetype."""
+ templates_by_lang: Dict[str, List[Dict[str, Any]]] = {}
+
+ for filepath in sorted(template_dir.rglob("*")):
+ if not filepath.is_file():
+ continue
+ rel_path = filepath.relative_to(template_dir)
+ if any(part.startswith(".") for part in rel_path.parts):
+ continue
+
+ lang = language_for(filepath, template_dir)
+ if lang is None:
+ continue
+
+ snippet = process_template_file(filepath, template_dir)
+ if snippet is not None:
+ templates_by_lang.setdefault(lang, []).append(snippet)
+
+ return templates_by_lang
+
+
+def write_snippet_files(templates_by_lang: Dict[str, List[Dict[str, Any]]], output_dir: Path) -> None:
+ """Write one <lang>.json per language and a package.json that lists them."""
+ output_dir.mkdir(parents=True, exist_ok=True)
+ contributed = []
+
+ for lang, snippets in sorted(templates_by_lang.items()):
+ snippet_obj = {snippet["prefix"]: snippet for snippet in snippets}
+ output_file = output_dir / f"{lang}.json"
+ output_file.write_text(
+ json.dumps(snippet_obj, indent=2, ensure_ascii=False) + "\n", encoding="utf-8"
+ )
+ contributed.append({"language": lang, "path": f"./{lang}.json"})
+ print(f"Created {output_file} with {len(snippet_obj)} snippets")
+
+ package = {
+ "name": "tmpl-snippets",
+ "contributes": {"snippets": contributed},
+ }
+ (output_dir / "package.json").write_text(
+ json.dumps(package, indent=2) + "\n", encoding="utf-8"
+ )
+
+
+def parse_args() -> argparse.Namespace:
+ parser = argparse.ArgumentParser(description=__doc__.splitlines()[0])
+ parser.add_argument(
+ "template_dir",
+ nargs="?",
+ type=Path,
+ default=Path(__file__).resolve().parent,
+ help="directory that holds the templates (default: this script's directory)",
+ )
+ parser.add_argument(
+ "--output",
+ type=Path,
+ default=Path.home() / ".config/nvim/snippets",
+ help="directory to write snippet files into (default: ~/.config/nvim/snippets)",
+ )
+ parser.add_argument(
+ "--dry-run",
+ action="store_true",
+ help="list the snippets that would be written, write nothing",
+ )
+ return parser.parse_args()
+
+
+def main() -> None:
+ args = parse_args()
+ templates_by_lang = collect_templates_by_language(args.template_dir)
+
+ if not templates_by_lang:
+ print("No templates with <++> placeholders found.")
+ return
+
+ if args.dry_run:
+ for lang, snippets in sorted(templates_by_lang.items()):
+ for snippet in snippets:
+ print(f"{lang}\t{snippet['prefix']}")
+ return
+
+ write_snippet_files(templates_by_lang, args.output)
+ print("\nDone. Load the snippets in Neovim with:")
+ print(f' require("luasnip.loaders.from_vscode").lazy_load({{ paths = {{ "{args.output}" }} }})')
+
+
+if __name__ == "__main__":
+ main()
diff --git a/test_convert_to_luasnip.py b/test_convert_to_luasnip.py
new file mode 100644
index 0000000..7490353
--- /dev/null
+++ b/test_convert_to_luasnip.py
@@ -0,0 +1,92 @@
+"""Tests for convert_to_luasnip."""
+
+import json
+import re
+from pathlib import Path
+
+from hypothesis import given
+from hypothesis import strategies as st
+
+import convert_to_luasnip as conv
+
+PLACEHOLDER = "<++>"
+
+
+def unescape(text: str) -> str:
+ """Reverse VSCode snippet escaping. Reference for the round trip."""
+ return re.sub(r"\\([\\$}])", r"\1", text)
+
+
+text_without_placeholder = st.text().filter(lambda s: "<+" not in s)
+
+
+@given(text_without_placeholder)
+def test_escape_round_trip(text):
+ body, count = conv.convert_placeholders(text)
+ assert count == 0
+ assert unescape(body) == text
+
+
+@given(st.lists(text_without_placeholder, min_size=1, max_size=6))
+def test_placeholder_count_matches_tab_stops(chunks):
+ source = PLACEHOLDER.join(chunks)
+ body, count = conv.convert_placeholders(source)
+ assert count == len(chunks) - 1
+ stops = re.findall(r"(?<!\\)\$\{(\d+)\}", body)
+ assert stops == [str(i) for i in range(1, count + 1)]
+ assert unescape(re.sub(r"(?<!\\)\$\{\d+\}", PLACEHOLDER, body)) == source
+
+
+def test_shell_variable_is_escaped():
+ body, _ = conv.convert_placeholders('for i do echo "$i"; done')
+ assert body == 'for i do echo "\\$i"; done'
+
+
+def test_make_variable_is_escaped():
+ body, _ = conv.convert_placeholders("$(FOLDER) : | <++>")
+ assert body == "\\$(FOLDER) : | ${1}"
+
+
+def test_backslash_and_brace_are_escaped():
+ body, _ = conv.convert_placeholders("printf %s\\\\n; { x; }")
+ assert body == "printf %s\\\\\\\\n; { x; \\}"
+
+
+def test_snippet_body_ends_with_final_tab_stop(tmp_path):
+ root = tmp_path / "tmpl"
+ (root / "sh").mkdir(parents=True)
+ (root / "sh" / "thing").write_text("echo <++>\n")
+ snippet = conv.process_template_file(root / "sh" / "thing", root)
+ assert snippet["body"] == ["echo ${1}", "$0"]
+
+
+def test_prefix_joins_path_parts(tmp_path):
+ root = tmp_path / "tmpl"
+ (root / "sh" / "trap").mkdir(parents=True)
+ f = root / "sh" / "trap" / "cleanup-temp"
+ f.write_text("<++>")
+ assert conv.generate_snippet_name(f, root) == "sh-trap-cleanup-temp"
+ (root / "c").mkdir()
+ g = root / "c" / "main.c"
+ g.write_text("<++>")
+ assert conv.generate_snippet_name(g, root) == "c-main"
+
+
+def test_common_lisp_maps_to_lisp_filetype():
+ assert conv.LANGUAGE_MAP["cl"] == "lisp"
+ assert conv.LANGUAGE_MAP["sh"] == "sh"
+
+
+def test_files_without_placeholder_are_skipped(tmp_path):
+ root = tmp_path / "tmpl"
+ (root / "sh").mkdir(parents=True)
+ (root / "sh" / "note").write_text("just prose\n")
+ assert conv.process_template_file(root / "sh" / "note", root) is None
+
+
+def test_write_creates_package_json(tmp_path):
+ out = tmp_path / "snippets"
+ conv.write_snippet_files({"sh": [{"prefix": "sh-x", "body": ["$1"], "description": "x"}]}, out)
+ package = json.loads((out / "package.json").read_text())
+ assert package["contributes"]["snippets"] == [{"language": "sh", "path": "./sh.json"}]
+ assert json.loads((out / "sh.json").read_text())["sh-x"]["prefix"] == "sh-x"